Excel Power Query in 2026: ETL for Data Analysts and Interview Questions
Master Excel Power Query for ETL operations, data transformation, and M language basics. Covers practical examples and common interview questions for data analyst roles.
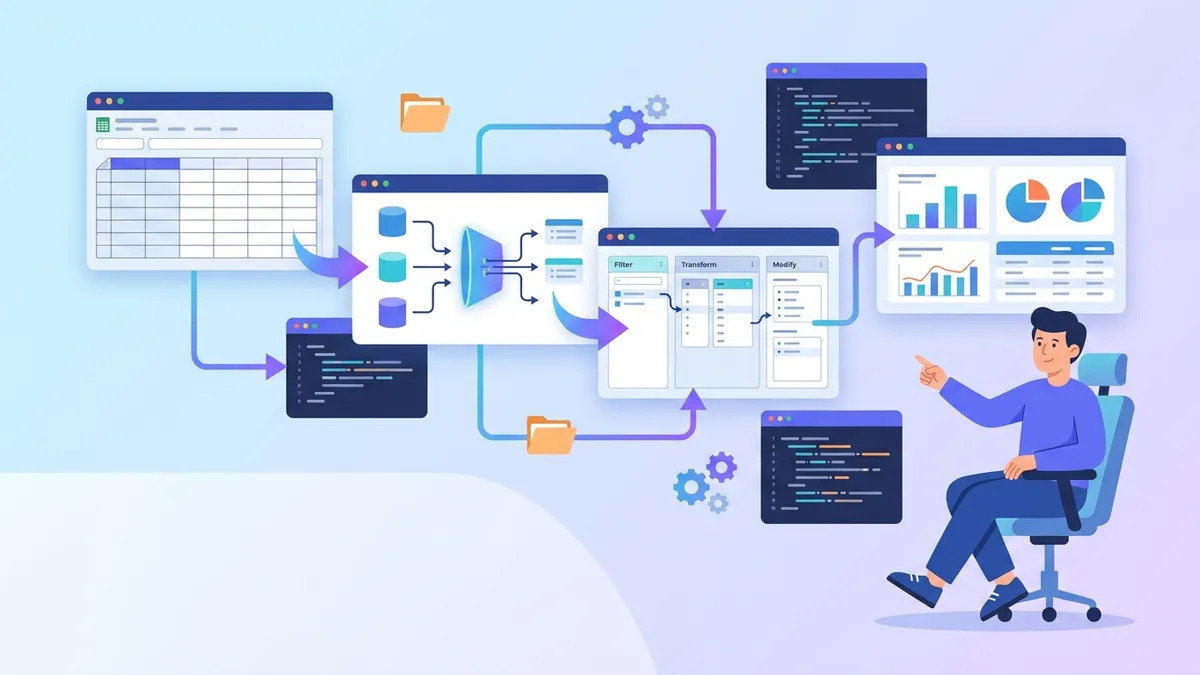
Excel Power Query transforms how data analysts handle ETL (Extract, Transform, Load) workflows directly within Excel. Unlike manual copy-paste or complex VBA macros, Power Query provides a visual interface backed by the M language, enabling repeatable data transformations that refresh with a single click.
Power Query is built into Excel 365, Excel 2021, Excel 2019, and Excel 2016. In earlier versions, it was available as a free add-in called "Power Query for Excel." The same engine powers Power BI Desktop dataflows.
What Power Query solves for data analysts
Data analysts spend significant time on data preparation: merging files from different sources, cleaning inconsistent formats, filtering irrelevant rows, and reshaping tables for analysis. Power Query addresses these tasks through a query editor that records each transformation step. When source data changes, the entire pipeline re-executes automatically.
The workflow follows three stages: connect to data sources, apply transformations, and load results into Excel tables or the data model. Each step is recorded in a formula bar using M language syntax, which can be edited directly for advanced scenarios.
This approach differs from traditional Excel formulas. While formulas recalculate cells, Power Query operates on entire tables before they reach the worksheet. A query that consolidates 50 CSV files, removes duplicates, and unpivots columns runs once and produces a clean table, rather than building complex nested formulas that slow down the workbook.
Connecting to data sources with Get Data
Power Query supports connections to files (CSV, Excel, JSON, XML), databases (SQL Server, MySQL, PostgreSQL, Oracle), cloud services (SharePoint, Azure, Salesforce), and web pages. The connection type determines what authentication and import options appear.
// Common data sources in Power Query
Data > Get Data > From File > From CSV
Data > Get Data > From Database > From SQL Server Database
Data > Get Data > From Other Sources > From Web
Data > Get Data > From Folder (multiple files)
The "From Folder" option is particularly useful for consolidating multiple files. Instead of importing each file separately, Power Query scans a folder, lists all matching files, and combines them into a single query. Adding a new file to the folder automatically includes it on the next refresh.
When connecting to a SQL database, Power Query can push transformation logic to the server through query folding. Filters and column selections translate into SQL WHERE and SELECT clauses, reducing the data transferred to Excel. The formula bar shows a "View Native Query" option when folding is active.
Core transformations in the Query Editor
The Query Editor provides ribbon commands for common operations, but understanding the underlying M code helps when customizations are needed. Each transformation adds a step to the "Applied Steps" pane, creating an auditable sequence.
Filtering and sorting rows
Filtering removes rows that do not meet criteria. The column header dropdown provides quick filters, while the "Filter Rows" dialog supports complex conditions with AND/OR logic.
// FilteredRows step in M language
let
    Source = Excel.CurrentWorkbook(){[Name="SalesData"]}[Content],
    FilteredRows = Table.SelectRows(Source, each [Region] = "EMEA" and [Amount] > 1000)
in
    FilteredRows
The Table.SelectRows function takes a table and a condition. The each keyword creates a function where _ represents the current row, and field access uses bracket notation [Region]. Multiple conditions combine with and or or operators.
Removing and renaming columns
Data sources often include columns that are not needed for analysis. Removing them early reduces memory usage and simplifies downstream steps.
// Remove columns, then rename remaining ones
let
    Source = Excel.CurrentWorkbook(){[Name="RawData"]}[Content],
    RemovedColumns = Table.RemoveColumns(Source, {"TempID", "InternalNotes", "Debug"}),
    RenamedColumns = Table.RenameColumns(RemovedColumns, {{"Cust_Name", "CustomerName"}, {"Amt", "Amount"}})
in
    RenamedColumns
The column list uses curly braces {} for multiple items. Renaming takes a list of pairs, where each pair contains the old name and new name. Consistent naming conventions across queries make combining datasets easier.
Splitting and merging columns
Text columns frequently need parsing. A "FullName" column might require splitting into first and last names, or separate date and time columns might need merging.
// Split FullName by delimiter into two columns
let
    Source = Excel.CurrentWorkbook(){[Name="Contacts"]}[Content],
    SplitColumn = Table.SplitColumn(Source, "FullName", Splitter.SplitTextByDelimiter(" ", QuoteStyle.Csv), {"FirstName", "LastName"})
in
    SplitColumn
The Splitter.SplitTextByDelimiter function handles the parsing logic. For more complex patterns, Splitter.SplitTextByEachDelimiter or Splitter.SplitTextByPositions offer additional control. When the number of resulting columns varies, Power Query creates columns dynamically.
Type conversions and data quality
Power Query infers column types on import, but explicit type assignment catches errors early. A text column containing numeric IDs should remain text if leading zeros matter. Date columns imported as text cause sorting issues.
// Explicit type assignments
let
    Source = Csv.Document(File.Contents("C:\Data\transactions.csv")),
    TypedColumns = Table.TransformColumnTypes(Source, {
        {"TransactionID", type text},
        {"Date", type date},
        {"Amount", type number},
        {"IsProcessed", type logical}
    })
in
    TypedColumns
The type keyword specifies the target type. Available types include text, number, date, datetime, datetimezone, time, duration, logical, and binary. Type errors surface as "Error" values in cells, making data quality issues visible before analysis.
Handling null values requires explicit logic. The Table.ReplaceValue function substitutes nulls with defaults, while Table.SelectRows with [Column] <> null filters them out.
Grouping and aggregation with Group By
Aggregating data by categories is a frequent requirement. The "Group By" transformation collapses rows sharing the same key values and applies aggregate functions.
// Group sales by region and year, calculate sum and count
let
    Source = Excel.CurrentWorkbook(){[Name="Sales"]}[Content],
    Grouped = Table.Group(Source, {"Region", "Year"}, {
        {"TotalSales", each List.Sum([Amount]), type number},
        {"OrderCount", each Table.RowCount(_), Int64.Type},
        {"AvgOrderValue", each List.Average([Amount]), type number}
    })
in
    Grouped
The grouping columns appear first, followed by aggregation definitions. Each aggregation specifies a new column name, an aggregation function, and an optional result type. The each keyword represents the subtable for each group, allowing any table or list function.
Nested aggregations enable calculations like "percentage of group total" by referencing both the row value and the group aggregate in a subsequent step.
Ready to ace your Data Analytics interviews?
Practice with our interactive simulators, flashcards, and technical tests.
Pivoting and unpivoting for reshaping data
Pivoting converts row values into columns, creating a crosstab layout. Unpivoting does the reverse, converting columns into rows for normalized structures.
// Unpivot month columns into rows
let
    Source = Excel.CurrentWorkbook(){[Name="MonthlySales"]}[Content],
    // Original: Product, Jan, Feb, Mar, Apr columns
    Unpivoted = Table.UnpivotOtherColumns(Source, {"Product"}, "Month", "Sales")
    // Result: Product, Month, Sales columns
in
    Unpivoted
The Table.UnpivotOtherColumns function keeps specified columns fixed and unpivots the rest. This is safer than listing all columns to unpivot, because adding new month columns automatically includes them. The two trailing parameters name the attribute column ("Month") and value column ("Sales").
Pivoting uses Table.Pivot with an aggregation function for cases where multiple values exist for the same row-column combination:
// Pivot sales by region
let
    Source = Excel.CurrentWorkbook(){[Name="DetailedSales"]}[Content],
    Pivoted = Table.Pivot(Source, List.Distinct(Source[Region]), "Region", "Amount", List.Sum)
in
    Pivoted
Merging and appending queries
Combining data from multiple sources is where Power Query reduces manual effort. Merging performs a join between two tables based on matching columns. Appending stacks tables vertically.
// Left join: Orders with Customer details
let
    Orders = Excel.CurrentWorkbook(){[Name="Orders"]}[Content],
    Customers = Excel.CurrentWorkbook(){[Name="Customers"]}[Content],
    Merged = Table.NestedJoin(Orders, {"CustomerID"}, Customers, {"ID"}, "CustomerDetails", JoinKind.LeftOuter),
    Expanded = Table.ExpandTableColumn(Merged, "CustomerDetails", {"Name", "Email"})
in
    Expanded
The Table.NestedJoin function creates a nested table column containing matching rows. The Table.ExpandTableColumn function then flattens the nested structure into regular columns. Join kinds include Inner, LeftOuter, RightOuter, FullOuter, LeftAnti, and RightAnti.
Appending with Table.Combine requires matching column names. When schemas differ, Table.SelectColumns on each source before combining ensures consistency:
// Append two sales tables with consistent columns
let
    Sales2024 = Table.SelectColumns(Source2024, {"Date", "Product", "Amount"}),
    Sales2025 = Table.SelectColumns(Source2025, {"Date", "Product", "Amount"}),
    Combined = Table.Combine({Sales2024, Sales2025})
in
    Combined
Custom columns and conditional logic
The "Add Column > Custom Column" feature allows calculated fields using M expressions. Conditional logic uses if-then-else syntax.
// Add a calculated column with conditional logic
let
    Source = Excel.CurrentWorkbook(){[Name="Orders"]}[Content],
    AddedColumn = Table.AddColumn(Source, "OrderCategory", each
        if [Amount] >= 10000 then "Enterprise"
        else if [Amount] >= 1000 then "Business"
        else "Consumer",
        type text
    )
in
    AddedColumn
The if expression must include both then and else branches. Nested conditions chain with else if. The final parameter specifies the column type, improving performance and preventing type inference issues.
For complex transformations, helper functions defined in the let block keep code readable:
let
    // Helper function for fiscal quarter
    GetFiscalQuarter = (date as date) as text =>
        let
            month = Date.Month(date),
            fiscalQ = if month >= 4 and month <= 6 then "Q1"
                     else if month >= 7 and month <= 9 then "Q2"
                     else if month >= 10 and month <= 12 then "Q3"
                     else "Q4"
        in
            fiscalQ,

    Source = Excel.CurrentWorkbook(){[Name="Transactions"]}[Content],
    AddedQuarter = Table.AddColumn(Source, "FiscalQuarter", each GetFiscalQuarter([Date]), type text)
in
    AddedQuarter
Error handling in Power Query
Transformation errors appear as "Error" values in cells rather than failing the entire query. The try-otherwise construct handles errors gracefully:
// Handle potential division errors
let
    Source = Excel.CurrentWorkbook(){[Name="Metrics"]}[Content],
    AddedRatio = Table.AddColumn(Source, "Ratio", each
        try [Value1] / [Value2] otherwise null,
        type number
    )
in
    AddedRatio
The try keyword attempts the expression and returns a record with HasError and Value fields. The otherwise clause provides a fallback when HasError is true. For more control, access the error details with try Expression:
// Capture error details
let
    result = try SomeRiskyFunction(),
    output = if result[HasError] then "Error: " & result[Error][Message] else result[Value]
in
    output
Power Query interview questions for data analysts
Interviewers assess both practical skills and understanding of when Power Query fits a workflow. These questions appear frequently in data analyst interviews.
What is query folding and why does it matter?
Query folding translates Power Query transformations into native queries for the data source. When connecting to SQL Server, a filter step becomes a WHERE clause executed on the server, reducing network transfer. Not all transformations fold: custom M functions, certain date manipulations, and operations after a non-folding step break the chain. Check folding status by right-clicking a step and looking for "View Native Query."
How does Power Query differ from Excel formulas for data transformation?
Excel formulas operate cell by cell within the worksheet and recalculate on every change. Power Query operates on tables before they reach the worksheet, processing data in bulk during refresh. For transformations like unpivoting, deduplication, or merging files, Power Query expresses the logic more directly than nested INDEX-MATCH or helper columns.
When would you choose Power Query over Power BI for ETL?
Power Query in Excel suits scenarios where analysts need transformed data in spreadsheet form for ad-hoc analysis, pivot tables, or sharing with users who do not have Power BI access. Power BI provides richer visualization, larger data capacity, and enterprise sharing features. The same M code works in both tools, so queries developed in Excel can migrate to Power BI Desktop without rewriting.
How do you handle data type mismatches when appending tables?
Set explicit types on each source table before combining with Table.Combine. If a column is text in one source and number in another, the append fails or produces errors. Use Table.TransformColumnTypes on both sources to enforce consistent types. The try-otherwise pattern handles edge cases where conversion fails for specific values.
Explain the difference between Merge and Append in Power Query.
Merge performs a horizontal join based on matching key columns, similar to SQL JOIN. Append performs a vertical union of rows from multiple tables, similar to SQL UNION ALL. Merge requires at least one common column for matching. Append requires columns with the same names to align properly.
For deeper preparation on SQL concepts that complement Power Query skills, the SQL window functions module covers ranking and aggregation patterns, while the SQL subqueries and CTEs module addresses query structuring techniques.
Loading options and refresh strategies
After transformations, the "Close & Load" button offers loading choices: load to a worksheet table, load only to the data model (Power Pivot), or create a connection-only query. Connection-only queries serve as staging steps for other queries without consuming worksheet space.
Refresh behavior depends on load destination. Worksheet tables refresh with the "Refresh All" button or can be set to refresh on file open. Data model tables participate in the workbook's data model refresh cycle. For queries connected to external databases, credential prompts may appear on refresh unless saved credentials exist.
Background refresh allows the workbook to remain usable during data loading, but creates complexity when downstream formulas depend on refreshed data. The "Enable background refresh" option in query properties controls this behavior. For critical reports, disabling background refresh ensures sequential execution.
Performance considerations for large datasets
Power Query can handle millions of rows, but workbook responsiveness depends on how data loads. Loading to the data model instead of worksheet tables avoids Excel's row limit and improves pivot table performance. Removing unnecessary columns early reduces memory footprint.
For queries that take several minutes, the "Data preview" in Query Editor shows only a sample. Transformations apply to the full dataset during refresh. Errors visible in preview indicate issues, but some errors appear only with full data. Running a test refresh on a subset validates the query before processing everything.
When consolidating many files, Power Query's binary combination feature processes files in parallel. Defining a function that transforms one file, then invoking it for each row in the file list, provides more control than the default combine approach.
The Microsoft documentation on Power Query best practices details optimization techniques including query dependency structures and buffer usage.
Power Query for repeatable ETL pipelines
The recorded steps in Power Query create documentation of the transformation logic. When requirements change, modifying a step updates all downstream steps automatically. This contrasts with ad-hoc Excel manipulations that require recreating from scratch when source data changes.
Teams can share queries by exporting connections or by storing query M code in version control. The Advanced Editor (View > Advanced Editor) displays the complete M script, which can be copied and pasted into another workbook. For enterprise scenarios, Power BI dataflows and Fabric provide centralized query management.
- Power Query handles ETL within Excel using recorded, repeatable transformation steps
- The M language underlying the visual interface enables customizations beyond ribbon commands
- Query folding pushes filters and projections to source databases for better performance
- Merge performs joins between tables, Append stacks tables vertically
- Type assignments and error handling prevent silent data quality issues
- Connection-only queries create reusable staging steps without worksheet output
- Interview questions focus on query folding, formula comparison, and merge versus append distinctions
Start practicing!
Test your knowledge with our interview simulators and technical tests.
Can you spot the bug in Data Analytics?
One real snippet, one hidden bug, one attempt a day. No account needed to try.

Written by
Anthony Fillion-MailletFounder of SharpSkill
Full-stack developer for over 10 years. Runs SharpSkill and answers for everything published here.
Updated on September 20, 2026
Share
Related articles
Data Analyst Interview Questions 2026: Complete SQL, Python and Analytics Guide
A comprehensive guide to data analyst interview questions covering SQL window functions, Python pandas operations, statistical concepts, and business analytics scenarios that companies ask in 2026.
Data Analyst Interview Questions Italy 2026: Advanced SQL, Python and Case Studies
Prepare for Data Analyst interviews in Italy with real questions from Italian companies in 2026. Covers advanced SQL, Python pandas, case studies, and the Italian hiring process.
Polars vs Pandas in 2026: Performance, Syntax and Data Analyst Interview Questions
Compare Polars and Pandas for Python data analysis in 2026. Benchmark results, syntax differences, lazy evaluation, and interview questions for data analyst roles.