Spring Batch 5 Interview: Partitioning, Chunks and Fault Tolerance
Ace your Spring Batch 5 interviews: 15 essential questions on partitioning, chunk-oriented processing, and fault tolerance with Java 21 code examples.
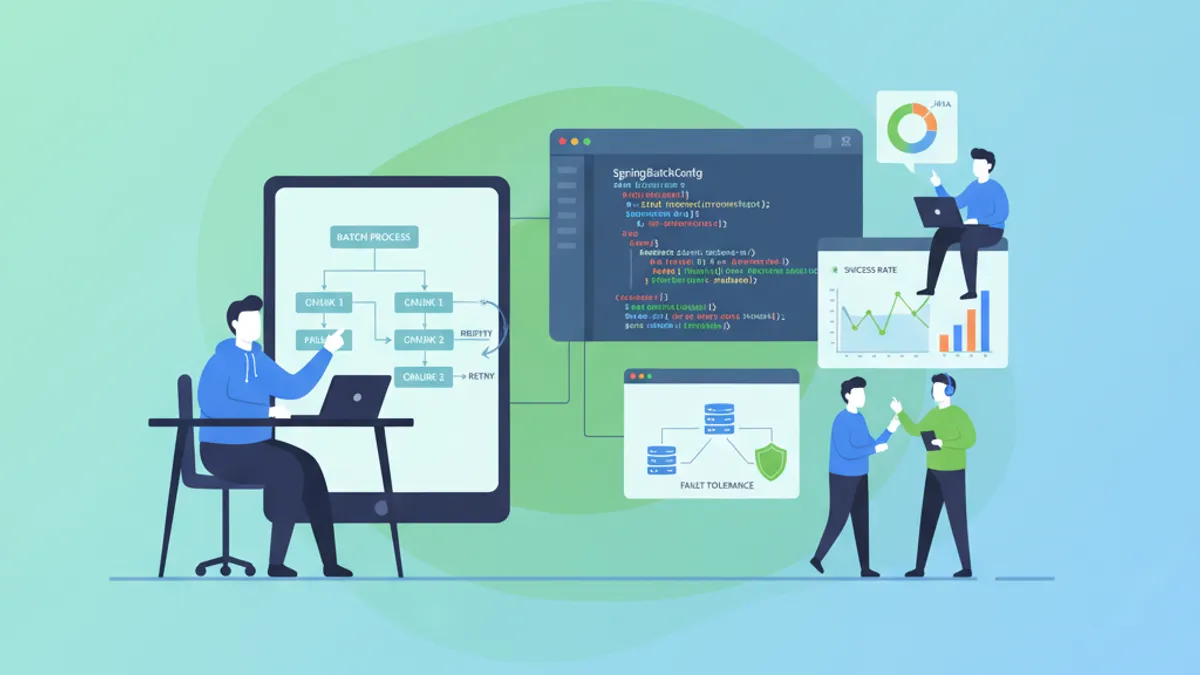
Spring Batch 5 stands as a cornerstone for enterprise-grade data processing in the Spring ecosystem. Technical interviews assess the ability to design robust, scalable, and fault-tolerant batch jobs. Mastering partitioning, chunk-oriented processing, and fault tolerance mechanisms sets senior developers apart.
Recruiters test deep understanding: why choose partitioning over remote chunking? How to size chunks properly? These architectural decisions reveal real production experience.
Spring Batch 5 Core Architecture
Question 1: What are the main components of Spring Batch?
Spring Batch architecture consists of three layers: the Application (jobs and business code), Batch Core (runtime classes to launch and control jobs), and Infrastructure (common readers, writers, and services like RetryTemplate).
// Spring Batch 5 job configuration with Java 21
@Configuration
public class BatchJobConfig {

    // JobRepository stores execution metadata
    // Enables restart and job monitoring
    private final JobRepository jobRepository;
    private final PlatformTransactionManager transactionManager;

    public BatchJobConfig(JobRepository jobRepository,
                          PlatformTransactionManager transactionManager) {
        this.jobRepository = jobRepository;
        this.transactionManager = transactionManager;
    }

    // A Job encapsulates the complete batch process
    // Composed of one or more Steps executed sequentially
    @Bean
    public Job importUserJob(Step processUsersStep, Step cleanupStep) {
        return new JobBuilder("importUserJob", jobRepository)
                .start(processUsersStep)      // Main processing step
                .next(cleanupStep)             // Cleanup step
                .build();
    }

    // A Step represents an independent unit of work
    // Two models: Tasklet (single task) or Chunk (iterative processing)
    @Bean
    public Step processUsersStep(ItemReader<UserRecord> reader,
                                  ItemProcessor<UserRecord, User> processor,
                                  ItemWriter<User> writer) {
        return new StepBuilder("processUsersStep", jobRepository)
                .<UserRecord, User>chunk(100, transactionManager)  // Commit every 100 items
                .reader(reader)       // Reads source data
                .processor(processor) // Transforms each item
                .writer(writer)       // Writes in batches of 100
                .build();
    }
}
The JobRepository persists execution state to the database. This persistence enables restarting a failed job exactly where it stopped, without reprocessing already committed data.
Question 2: What is the difference between Tasklet and Chunk-oriented processing?
Tasklet executes a discrete, non-repetitive action: file deletion, stored procedure call, notification email. Chunk processes massive volumes by splitting data into manageable batches.
// Tasklet: single action without iteration
@Component
public class CleanupTasklet implements Tasklet {

    private final Path tempDirectory = Path.of("/tmp/batch-work");

    @Override
    public RepeatStatus execute(StepContribution contribution,
                                 ChunkContext chunkContext) throws Exception {
        // Deletes all temporary files from processing
        try (var files = Files.walk(tempDirectory)) {
            files.filter(Files::isRegularFile)
                 .forEach(this::deleteQuietly);
        }

        // FINISHED indicates the tasklet completed its work
        // CONTINUABLE would restart execution (useful for polling)
        return RepeatStatus.FINISHED;
    }

    private void deleteQuietly(Path file) {
        try {
            Files.delete(file);
        } catch (IOException e) {
            // Log and continue - don't fail the job for one file
        }
    }
}// Chunk-oriented: high-volume processing
@Configuration
public class ChunkProcessingConfig {
@Bean
public Step processOrdersStep(JobRepository jobRepository,
PlatformTransactionManager transactionManager,
ItemReader<OrderRecord> reader,
ItemProcessor<OrderRecord, ProcessedOrder> processor,
ItemWriter<ProcessedOrder> writer) {
return new StepBuilder("processOrdersStep", jobRepository)
// Chunk of 500: reads 500 items, processes, writes, then commits
.<OrderRecord, ProcessedOrder>chunk(500, transactionManager)
.reader(reader)
.processor(processor)
.writer(writer)
// Listener to monitor progress
.listener(new ChunkProgressListener())
.build();
}
}Chunk-oriented processing provides critical benefits: optimized memory management (only the current chunk in memory), granular transactions (commit per chunk), and failure recovery at the last committed chunk.
Deep Dive into Chunk-Oriented Processing
Question 3: How does the chunk lifecycle work?
Each chunk follows a precise cycle: reading items one by one until reaching the configured size, processing each item individually, then writing the group. A transaction wraps the entire chunk.
// ItemReader: reads one item at a time
@StepScope
@Component
public class OrderItemReader implements ItemReader<OrderRecord> {

    // @StepScope: new instance per step execution
    // Enables injecting dynamic job parameters
    @Value("#{jobParameters['startDate']}")
    private LocalDate startDate;

    private Iterator<OrderRecord> orderIterator;

    @BeforeStep
    public void initializeReader(StepExecution stepExecution) {
        // Loads data at step startup
        List<OrderRecord> orders = fetchOrdersFromDate(startDate);
        this.orderIterator = orders.iterator();
    }

    @Override
    public OrderRecord read() {
        // Returns null to signal end of data
        // Spring Batch calls read() until receiving null
        if (orderIterator.hasNext()) {
            return orderIterator.next();
        }
        return null;  // End of dataset
    }

    private List<OrderRecord> fetchOrdersFromDate(LocalDate date) {
        // Fetches from data source
        return List.of();  // Actual implementation
    }
}// ItemProcessor: transforms each item individually
@Component
public class OrderItemProcessor implements ItemProcessor<OrderRecord, ProcessedOrder> {
private final PricingService pricingService;
private final ValidationService validationService;
public OrderItemProcessor(PricingService pricingService,
ValidationService validationService) {
this.pricingService = pricingService;
this.validationService = validationService;
}
@Override
public ProcessedOrder process(OrderRecord item) {
// Returning null filters the item (won't be written)
if (!validationService.isValid(item)) {
return null; // Item filtered
}
// Business transformation
BigDecimal finalPrice = pricingService.calculatePrice(item);
return new ProcessedOrder(
item.orderId(),
item.customerId(),
finalPrice,
LocalDateTime.now()
);
}
}// ItemWriter: writes the complete chunk in one operation
@Component
public class OrderItemWriter implements ItemWriter<ProcessedOrder> {
private final JdbcTemplate jdbcTemplate;
public OrderItemWriter(JdbcTemplate jdbcTemplate) {
this.jdbcTemplate = jdbcTemplate;
}
@Override
public void write(Chunk<? extends ProcessedOrder> chunk) {
// The chunk contains all processed items
// Batch writing for optimized performance
List<? extends ProcessedOrder> items = chunk.getItems();
jdbcTemplate.batchUpdate(
"INSERT INTO processed_orders (order_id, customer_id, final_price, processed_at) VALUES (?, ?, ?, ?)",
items,
items.size(),
(ps, order) -> {
ps.setLong(1, order.orderId());
ps.setLong(2, order.customerId());
ps.setBigDecimal(3, order.finalPrice());
ps.setTimestamp(4, Timestamp.valueOf(order.processedAt()));
}
);
}
}If an exception occurs during chunk processing, the transaction rolls back. The job can then resume from that chunk using metadata stored in the JobRepository.
Question 4: How to choose the optimal chunk size?
Chunk size directly impacts performance and memory consumption. A chunk too small multiplies commits (overhead). A chunk too large consumes excessive memory and lengthens rollbacks on failure.
// Dynamic chunk size configuration
@Configuration
public class ChunkSizingConfig {

    // Reasonable default for most cases
    private static final int DEFAULT_CHUNK_SIZE = 100;

    // For lightweight items (few fields)
    private static final int LIGHT_ITEMS_CHUNK_SIZE = 500;

    // For heavyweight items (blobs, documents)
    private static final int HEAVY_ITEMS_CHUNK_SIZE = 25;

    @Bean
    public Step processLightDataStep(JobRepository jobRepository,
                                      PlatformTransactionManager txManager,
                                      ItemReader<LightRecord> reader,
                                      ItemWriter<LightRecord> writer) {
        return new StepBuilder("processLightDataStep", jobRepository)
                // Lightweight items: larger chunks for fewer commits
                .<LightRecord, LightRecord>chunk(LIGHT_ITEMS_CHUNK_SIZE, txManager)
                .reader(reader)
                .writer(writer)
                .build();
    }

    @Bean
    public Step processDocumentsStep(JobRepository jobRepository,
                                      PlatformTransactionManager txManager,
                                      ItemReader<Document> reader,
                                      ItemProcessor<Document, ProcessedDocument> processor,
                                      ItemWriter<ProcessedDocument> writer) {
        return new StepBuilder("processDocumentsStep", jobRepository)
                // Heavy documents: smaller chunks to limit memory
                .<Document, ProcessedDocument>chunk(HEAVY_ITEMS_CHUNK_SIZE, txManager)
                .reader(reader)
                .processor(processor)
                .writer(writer)
                .build();
    }
}Start with 100 items per chunk, then adjust based on metrics: commit time, memory usage, and rollback duration. Use listeners to monitor and identify the sweet spot.
Partitioning for Parallel Processing
Question 5: What is partitioning and when should it be used?
Partitioning divides a dataset into independent partitions processed in parallel. Each partition executes in its own thread (local) or on a remote worker. This approach multiplies throughput without sacrificing restartability.
// Partitioned job configuration
@Configuration
public class PartitionedJobConfig {

    private final JobRepository jobRepository;
    private final PlatformTransactionManager transactionManager;

    public PartitionedJobConfig(JobRepository jobRepository,
                                 PlatformTransactionManager transactionManager) {
        this.jobRepository = jobRepository;
        this.transactionManager = transactionManager;
    }

    @Bean
    public Job partitionedImportJob(Step partitionedStep) {
        return new JobBuilder("partitionedImportJob", jobRepository)
                .start(partitionedStep)
                .build();
    }

    // Manager step: orchestrates partitions
    @Bean
    public Step partitionedStep(Partitioner partitioner,
                                 Step workerStep,
                                 TaskExecutor taskExecutor) {
        return new StepBuilder("partitionedStep", jobRepository)
                // Divides work via the Partitioner
                .partitioner("workerStep", partitioner)
                // Step executed for each partition
                .step(workerStep)
                // 8 parallel threads
                .taskExecutor(taskExecutor)
                // Number of partitions to create
                .gridSize(8)
                .build();
    }

    // TaskExecutor for parallel execution
    @Bean
    public TaskExecutor batchTaskExecutor() {
        ThreadPoolTaskExecutor executor = new ThreadPoolTaskExecutor();
        executor.setCorePoolSize(8);
        executor.setMaxPoolSize(16);
        executor.setQueueCapacity(50);
        executor.setThreadNamePrefix("batch-partition-");
        executor.initialize();
        return executor;
    }
}// Partitioner based on ID ranges
@Component
public class RangePartitioner implements Partitioner {
private final JdbcTemplate jdbcTemplate;
public RangePartitioner(JdbcTemplate jdbcTemplate) {
this.jdbcTemplate = jdbcTemplate;
}
@Override
public Map<String, ExecutionContext> partition(int gridSize) {
// Retrieves dataset boundaries
Long minId = jdbcTemplate.queryForObject(
"SELECT MIN(id) FROM orders WHERE status = 'PENDING'", Long.class);
Long maxId = jdbcTemplate.queryForObject(
"SELECT MAX(id) FROM orders WHERE status = 'PENDING'", Long.class);
if (minId == null || maxId == null) {
return Map.of(); // No data to process
}
// Calculates each partition size
long range = (maxId - minId) / gridSize + 1;
Map<String, ExecutionContext> partitions = new HashMap<>();
for (int i = 0; i < gridSize; i++) {
ExecutionContext context = new ExecutionContext();
long start = minId + (i * range);
long end = Math.min(start + range - 1, maxId);
// Each partition receives its boundaries
context.putLong("minId", start);
context.putLong("maxId", end);
context.putInt("partitionNumber", i);
partitions.put("partition" + i, context);
}
return partitions;
}
}Partitioning suits large datasets where items are independent. Partitions must be balanced to prevent a slow partition from slowing down the entire job.
Question 6: What is the difference between local and remote partitioning?
Local partitioning executes all partitions on the same JVM with a thread pool. Remote partitioning distributes partitions across multiple JVMs (workers) via messaging middleware.
// Remote partitioning configuration with messaging
@Configuration
public class RemotePartitioningConfig {

    @Bean
    public Step managerStep(JobRepository jobRepository,
                             Partitioner partitioner,
                             MessageChannelPartitionHandler partitionHandler) {
        return new StepBuilder("managerStep", jobRepository)
                .partitioner("workerStep", partitioner)
                // Handler that communicates with remote workers
                .partitionHandler(partitionHandler)
                .build();
    }

    // PartitionHandler sends ExecutionContexts to workers
    @Bean
    public MessageChannelPartitionHandler partitionHandler(
            MessagingTemplate messagingTemplate,
            JobExplorer jobExplorer) {
        MessageChannelPartitionHandler handler = new MessageChannelPartitionHandler();
        handler.setStepName("workerStep");
        handler.setGridSize(4);
        handler.setMessagingOperations(messagingTemplate);
        handler.setJobExplorer(jobExplorer);
        // Timeout waiting for workers to complete
        handler.setPollInterval(5000L);
        return handler;
    }
}// Worker-side configuration
@Configuration
public class WorkerConfiguration {
private final JobRepository jobRepository;
private final PlatformTransactionManager transactionManager;
public WorkerConfiguration(JobRepository jobRepository,
PlatformTransactionManager transactionManager) {
this.jobRepository = jobRepository;
this.transactionManager = transactionManager;
}
// Worker receives partitions and executes the step
@Bean
public Step workerStep(ItemReader<OrderRecord> reader,
ItemProcessor<OrderRecord, ProcessedOrder> processor,
ItemWriter<ProcessedOrder> writer) {
return new StepBuilder("workerStep", jobRepository)
.<OrderRecord, ProcessedOrder>chunk(100, transactionManager)
// Reader configured with @StepScope to receive partition parameters
.reader(reader)
.processor(processor)
.writer(writer)
.build();
}
// Reader that uses partition boundaries
@Bean
@StepScope
public JdbcCursorItemReader<OrderRecord> partitionedReader(
DataSource dataSource,
@Value("#{stepExecutionContext['minId']}") Long minId,
@Value("#{stepExecutionContext['maxId']}") Long maxId) {
return new JdbcCursorItemReaderBuilder<OrderRecord>()
.name("partitionedOrderReader")
.dataSource(dataSource)
.sql("SELECT * FROM orders WHERE id BETWEEN ? AND ? AND status = 'PENDING'")
.preparedStatementSetter(ps -> {
ps.setLong(1, minId);
ps.setLong(2, maxId);
})
.rowMapper(new OrderRecordRowMapper())
.build();
}
}Ready to ace your Spring Boot interviews?
Practice with our interactive simulators, flashcards, and technical tests.
Fault Tolerance and Error Recovery
Question 7: What fault tolerance mechanisms does Spring Batch offer?
Spring Batch provides three complementary mechanisms: skip (ignore failing items), retry (automatically retry), and restart (resume a failed job). These mechanisms are configured at the step level.
// Complete fault tolerance configuration
@Configuration
public class FaultTolerantStepConfig {

    @Bean
    public Step faultTolerantStep(JobRepository jobRepository,
                                   PlatformTransactionManager transactionManager,
                                   ItemReader<DataRecord> reader,
                                   ItemProcessor<DataRecord, ProcessedRecord> processor,
                                   ItemWriter<ProcessedRecord> writer,
                                   SkipPolicy customSkipPolicy) {
        return new StepBuilder("faultTolerantStep", jobRepository)
                .<DataRecord, ProcessedRecord>chunk(100, transactionManager)
                .reader(reader)
                .processor(processor)
                .writer(writer)
                // Enables fault tolerant mode
                .faultTolerant()
                // SKIP: ignores up to 10 validation errors
                .skipLimit(10)
                .skip(ValidationException.class)
                .skip(DataIntegrityViolationException.class)
                // Some errors should never be skipped
                .noSkip(FatalBatchException.class)
                // RETRY: retries transient errors
                .retryLimit(3)
                .retry(TransientDataAccessException.class)
                .retry(DeadlockLoserDataAccessException.class)
                // Exponential backoff between retries
                .backOffPolicy(exponentialBackOffPolicy())
                // Listener to log skips
                .listener(skipListener())
                .build();
    }

    @Bean
    public BackOffPolicy exponentialBackOffPolicy() {
        ExponentialBackOffPolicy policy = new ExponentialBackOffPolicy();
        policy.setInitialInterval(1000);  // 1 second
        policy.setMultiplier(2.0);         // Doubles each retry
        policy.setMaxInterval(10000);      // Max 10 seconds
        return policy;
    }

    @Bean
    public SkipListener<DataRecord, ProcessedRecord> skipListener() {
        return new SkipListener<>() {
            @Override
            public void onSkipInRead(Throwable t) {
                // Log unreadable item
            }

            @Override
            public void onSkipInProcess(DataRecord item, Throwable t) {
                // Log item that failed processing
            }

            @Override
            public void onSkipInWrite(ProcessedRecord item, Throwable t) {
                // Log item that failed writing
            }
        };
    }
}
Retry suits transient errors (network timeout, database deadlock). Skip suits individual data errors that should not block overall processing.
Question 8: How to implement a custom SkipPolicy?
A custom SkipPolicy enables fine-grained decision logic: skip based on exception type, error count, or specific business criteria.
// SkipPolicy with advanced business logic
@Component
public class AdaptiveSkipPolicy implements SkipPolicy {

    private static final int MAX_SKIP_COUNT = 100;
    private static final double MAX_SKIP_PERCENTAGE = 0.05;  // 5% max

    private final AtomicInteger totalProcessed = new AtomicInteger(0);
    private final AtomicInteger skipCount = new AtomicInteger(0);

    @Override
    public boolean shouldSkip(Throwable exception, long skipCountSoFar) {
        // Never skip fatal errors
        if (exception instanceof FatalBatchException
                || exception instanceof OutOfMemoryError) {
            return false;
        }

        // Absolute skip limit
        if (skipCountSoFar >= MAX_SKIP_COUNT) {
            return false;  // Stop the job
        }

        // Percentage limit
        int total = totalProcessed.get();
        if (total > 1000) {  // Apply only after warmup
            double skipPercentage = (double) skipCountSoFar / total;
            if (skipPercentage > MAX_SKIP_PERCENTAGE) {
                return false;  // Too many errors proportionally
            }
        }

        // Skip validation and data errors
        return exception instanceof ValidationException
                || exception instanceof DataFormatException
                || exception instanceof IllegalArgumentException;
    }

    // Called by a listener to track progress
    public void incrementProcessed() {
        totalProcessed.incrementAndGet();
    }
}
Question 9: How does restarting a failed job work?
The JobRepository stores each execution's state. On restart, Spring Batch identifies the last committed chunk and resumes from that point. Successfully processed items are not reprocessed.
// Job restart management service
@Service
public class JobRestartService {

    private final JobLauncher jobLauncher;
    private final JobExplorer jobExplorer;
    private final JobRepository jobRepository;
    private final Job importJob;

    public JobRestartService(JobLauncher jobLauncher,
                              JobExplorer jobExplorer,
                              JobRepository jobRepository,
                              @Qualifier("importJob") Job importJob) {
        this.jobLauncher = jobLauncher;
        this.jobExplorer = jobExplorer;
        this.jobRepository = jobRepository;
        this.importJob = importJob;
    }

    public JobExecution restartFailedJob(Long jobExecutionId) throws Exception {
        // Retrieves the failed execution
        JobExecution failedExecution = jobExplorer.getJobExecution(jobExecutionId);

        if (failedExecution == null) {
            throw new IllegalArgumentException("Job execution not found: " + jobExecutionId);
        }

        // Verifies the job can be restarted
        if (!failedExecution.getStatus().equals(BatchStatus.FAILED)) {
            throw new IllegalStateException("Only FAILED jobs can be restarted");
        }

        // Uses the same parameters as the original execution
        JobParameters originalParams = failedExecution.getJobParameters();

        // Relaunches the job - automatically resumes from last checkpoint
        return jobLauncher.run(importJob, originalParams);
    }

    public List<JobExecution> findRestartableJobs() {
        // Lists all FAILED executions not yet restarted
        return jobExplorer.findJobInstancesByJobName(importJob.getName(), 0, 100)
                .stream()
                .flatMap(instance -> jobExplorer.getJobExecutions(instance).stream())
                .filter(exec -> exec.getStatus() == BatchStatus.FAILED)
                .filter(this::isRestartable)
                .toList();
    }

    private boolean isRestartable(JobExecution execution) {
        // Verifies no more recent successful execution exists
        JobInstance instance = execution.getJobInstance();
        return jobExplorer.getJobExecutions(instance).stream()
                .noneMatch(exec -> exec.getStatus() == BatchStatus.COMPLETED);
    }
}A job can only be restarted if JobParameters are identical. Modifying a parameter creates a new job instance, losing the progress history.
Scaling and Optimization
Question 10: What scaling strategies are available?
Spring Batch offers four strategies: multi-threaded step (multiple threads read in parallel), parallel steps (independent steps in parallel), remote chunking (distributed processing), and partitioning (distributed data).
// Multi-threaded step: multiple threads process the same dataset
@Configuration
public class MultiThreadedStepConfig {

    @Bean
    public Step multiThreadedStep(JobRepository jobRepository,
                                   PlatformTransactionManager transactionManager,
                                   ItemReader<Record> reader,
                                   ItemProcessor<Record, ProcessedRecord> processor,
                                   ItemWriter<ProcessedRecord> writer,
                                   TaskExecutor taskExecutor) {
        return new StepBuilder("multiThreadedStep", jobRepository)
                .<Record, ProcessedRecord>chunk(100, transactionManager)
                // CAUTION: reader must be thread-safe
                .reader(synchronizedReader(reader))
                .processor(processor)
                .writer(writer)
                // 4 threads process chunks in parallel
                .taskExecutor(taskExecutor)
                .throttleLimit(4)
                .build();
    }

    // Wrapper to make the reader thread-safe
    private ItemReader<Record> synchronizedReader(ItemReader<Record> reader) {
        SynchronizedItemStreamReader<Record> syncReader = new SynchronizedItemStreamReader<>();
        syncReader.setDelegate((ItemStreamReader<Record>) reader);
        return syncReader;
    }
}// Executing independent steps in parallel
@Configuration
public class ParallelStepsConfig {
@Bean
public Job parallelJob(JobRepository jobRepository,
Step loadCustomersStep,
Step loadProductsStep,
Step loadOrdersStep,
Step processDataStep) {
// Parallel flow: customers and products loaded simultaneously
Flow loadCustomersFlow = new FlowBuilder<Flow>("loadCustomersFlow")
.start(loadCustomersStep)
.build();
Flow loadProductsFlow = new FlowBuilder<Flow>("loadProductsFlow")
.start(loadProductsStep)
.build();
Flow loadOrdersFlow = new FlowBuilder<Flow>("loadOrdersFlow")
.start(loadOrdersStep)
.build();
// Split executes flows in parallel
return new JobBuilder("parallelJob", jobRepository)
.start(new FlowBuilder<Flow>("parallelLoadFlow")
.split(new SimpleAsyncTaskExecutor())
.add(loadCustomersFlow, loadProductsFlow, loadOrdersFlow)
.build())
// After parallel loading, sequential processing
.next(processDataStep)
.build()
.build();
}
}Multi-threading suits cases where the reader can be synchronized. Partitioning is preferred for large volumes since each partition has its own reader without contention.
Question 11: How to monitor job performance?
Spring Batch exposes metrics via listeners and JobRepository. Integration with Micrometer enables export to Prometheus, Grafana, or other monitoring systems.
// Monitoring configuration with Micrometer
@Configuration
public class BatchMetricsConfig {

    private final MeterRegistry meterRegistry;

    public BatchMetricsConfig(MeterRegistry meterRegistry) {
        this.meterRegistry = meterRegistry;
    }

    @Bean
    public JobExecutionListener metricsJobListener() {
        return new JobExecutionListener() {

            private Timer.Sample jobTimer;

            @Override
            public void beforeJob(JobExecution jobExecution) {
                // Starts the job duration timer
                jobTimer = Timer.start(meterRegistry);
                Counter.builder("batch.job.started")
                        .tag("job", jobExecution.getJobInstance().getJobName())
                        .register(meterRegistry)
                        .increment();
            }

            @Override
            public void afterJob(JobExecution jobExecution) {
                // Records total duration
                jobTimer.stop(Timer.builder("batch.job.duration")
                        .tag("job", jobExecution.getJobInstance().getJobName())
                        .tag("status", jobExecution.getStatus().toString())
                        .register(meterRegistry));

                // Job counter by status
                Counter.builder("batch.job.completed")
                        .tag("job", jobExecution.getJobInstance().getJobName())
                        .tag("status", jobExecution.getStatus().toString())
                        .register(meterRegistry)
                        .increment();
            }
        };
    }

    @Bean
    public StepExecutionListener metricsStepListener() {
        return new StepExecutionListener() {

            @Override
            public void afterStep(StepExecution stepExecution) {
                String jobName = stepExecution.getJobExecution().getJobInstance().getJobName();
                String stepName = stepExecution.getStepName();

                // Throughput metrics
                Gauge.builder("batch.step.read.count", stepExecution, StepExecution::getReadCount)
                        .tag("job", jobName)
                        .tag("step", stepName)
                        .register(meterRegistry);

                Gauge.builder("batch.step.write.count", stepExecution, StepExecution::getWriteCount)
                        .tag("job", jobName)
                        .tag("step", stepName)
                        .register(meterRegistry);

                Gauge.builder("batch.step.skip.count", stepExecution, StepExecution::getSkipCount)
                        .tag("job", jobName)
                        .tag("step", stepName)
                        .register(meterRegistry);

                return null;
            }
        };
    }
}
Question 12: What are common pitfalls with partitioning?
Frequent mistakes include: unbalanced partitions (one partition contains 90% of data), non-thread-safe readers, and incorrect state management between partitions.
// Partitioner that actually balances the load
@Component
public class BalancedPartitioner implements Partitioner {

    private final JdbcTemplate jdbcTemplate;

    public BalancedPartitioner(JdbcTemplate jdbcTemplate) {
        this.jdbcTemplate = jdbcTemplate;
    }

    @Override
    public Map<String, ExecutionContext> partition(int gridSize) {
        // Counts total items to process
        Integer totalCount = jdbcTemplate.queryForObject(
                "SELECT COUNT(*) FROM orders WHERE status = 'PENDING'", Integer.class);

        if (totalCount == null || totalCount == 0) {
            return Map.of();
        }

        // Calculates target size per partition
        int itemsPerPartition = (int) Math.ceil((double) totalCount / gridSize);

        Map<String, ExecutionContext> partitions = new HashMap<>();

        // Uses OFFSET/LIMIT for balanced partitions
        // More expensive than ranges but guarantees balance
        for (int i = 0; i < gridSize; i++) {
            ExecutionContext context = new ExecutionContext();
            context.putInt("offset", i * itemsPerPartition);
            context.putInt("limit", itemsPerPartition);
            context.putInt("partitionNumber", i);

            partitions.put("partition" + i, context);
        }

        return partitions;
    }
}

// OffsetBasedReader.java
// Reader compatible with offset-based partitioning
@StepScope
@Component
public class OffsetBasedReader implements ItemReader<OrderRecord>, ItemStream {

    private final JdbcTemplate jdbcTemplate;
    private Iterator<OrderRecord> iterator;

    @Value("#{stepExecutionContext['offset']}")
    private int offset;

    @Value("#{stepExecutionContext['limit']}")
    private int limit;

    public OffsetBasedReader(JdbcTemplate jdbcTemplate) {
        this.jdbcTemplate = jdbcTemplate;
    }

    @Override
    public void open(ExecutionContext executionContext) {
        // Loads exactly the portion assigned to this partition
        List<OrderRecord> records = jdbcTemplate.query(
                "SELECT * FROM orders WHERE status = 'PENDING' ORDER BY id LIMIT ? OFFSET ?",
                new OrderRecordRowMapper(),
                limit, offset
        );
        this.iterator = records.iterator();
    }

    @Override
    public OrderRecord read() {
        return iterator.hasNext() ? iterator.next() : null;
    }

    @Override
    public void update(ExecutionContext executionContext) {
        // State saving for restart if needed
    }

    @Override
    public void close() {
        // Cleanup
    }
}
Advanced Questions for Seniors
Question 13: How to handle dependencies between jobs?
Spring Batch doesn't natively manage inter-job dependencies. Solutions include: external orchestrators (Airflow, Kubernetes CronJob), or custom implementation with JobExplorer.
// Inter-job dependency management
@Service
public class JobDependencyService {

    private final JobExplorer jobExplorer;
    private final JobLauncher jobLauncher;
    private final Map<String, Job> jobs;

    public JobDependencyService(JobExplorer jobExplorer,
                                  JobLauncher jobLauncher,
                                  Map<String, Job> jobs) {
        this.jobExplorer = jobExplorer;
        this.jobLauncher = jobLauncher;
        this.jobs = jobs;
    }

    public JobExecution runWithDependencies(String jobName,
                                             JobParameters params,
                                             List<String> dependsOn) throws Exception {
        // Verifies all dependencies succeeded
        for (String dependency : dependsOn) {
            if (!hasSuccessfulExecution(dependency, params)) {
                throw new JobExecutionException(
                        "Dependency not satisfied: " + dependency);
            }
        }

        Job job = jobs.get(jobName);
        if (job == null) {
            throw new IllegalArgumentException("Unknown job: " + jobName);
        }

        return jobLauncher.run(job, params);
    }

    private boolean hasSuccessfulExecution(String jobName, JobParameters params) {
        // Looks for a COMPLETED execution with the same business parameters
        return jobExplorer.findJobInstancesByJobName(jobName, 0, 1)
                .stream()
                .flatMap(instance -> jobExplorer.getJobExecutions(instance).stream())
                .filter(exec -> exec.getStatus() == BatchStatus.COMPLETED)
                .anyMatch(exec -> matchesBusinessParams(exec.getJobParameters(), params));
    }

    private boolean matchesBusinessParams(JobParameters actual, JobParameters expected) {
        // Compares business parameters (ignores execution timestamps)
        String actualDate = actual.getString("businessDate");
        String expectedDate = expected.getString("businessDate");
        return Objects.equals(actualDate, expectedDate);
    }
}
Question 14: How to effectively test a Spring Batch job?
Testing Spring Batch jobs requires a layered approach: unit tests for components (reader, processor, writer), integration tests for steps, and end-to-end tests for complete jobs.
// Processor unit test
@ExtendWith(MockitoExtension.class)
class OrderProcessorTest {

    @Mock
    private PricingService pricingService;

    @Mock
    private ValidationService validationService;

    @InjectMocks
    private OrderItemProcessor processor;

    @Test
    void shouldProcessValidOrder() {
        // Given
        OrderRecord input = new OrderRecord(1L, 100L, BigDecimal.TEN);
        when(validationService.isValid(input)).thenReturn(true);
        when(pricingService.calculatePrice(input)).thenReturn(new BigDecimal("12.50"));

        // When
        ProcessedOrder result = processor.process(input);

        // Then
        assertThat(result).isNotNull();
        assertThat(result.finalPrice()).isEqualTo(new BigDecimal("12.50"));
    }

    @Test
    void shouldFilterInvalidOrder() {
        // Given
        OrderRecord input = new OrderRecord(1L, 100L, BigDecimal.TEN);
        when(validationService.isValid(input)).thenReturn(false);

        // When
        ProcessedOrder result = processor.process(input);

        // Then - null means filtered
        assertThat(result).isNull();
        verify(pricingService, never()).calculatePrice(any());
    }
}// Complete job integration test
@SpringBatchTest
@SpringBootTest
@ActiveProfiles("test")
class ImportJobIntegrationTest {
@Autowired
private JobLauncherTestUtils jobLauncherTestUtils;
@Autowired
private JobRepositoryTestUtils jobRepositoryTestUtils;
@Autowired
private JdbcTemplate jdbcTemplate;
@BeforeEach
void setup() {
// Cleans metadata between tests
jobRepositoryTestUtils.removeJobExecutions();
// Resets test data
jdbcTemplate.execute("DELETE FROM processed_orders");
jdbcTemplate.execute("DELETE FROM orders");
}
@Test
void shouldCompleteJobSuccessfully() throws Exception {
// Given - test data
insertTestOrders(100);
// When
JobParameters params = new JobParametersBuilder()
.addLocalDate("businessDate", LocalDate.now())
.addLong("run.id", System.currentTimeMillis())
.toJobParameters();
JobExecution execution = jobLauncherTestUtils.launchJob(params);
// Then
assertThat(execution.getStatus()).isEqualTo(BatchStatus.COMPLETED);
assertThat(countProcessedOrders()).isEqualTo(100);
}
@Test
void shouldHandleEmptyDataset() throws Exception {
// Given - no data
// When
JobExecution execution = jobLauncherTestUtils.launchJob();
// Then - job succeeds even without data
assertThat(execution.getStatus()).isEqualTo(BatchStatus.COMPLETED);
}
@Test
void shouldRestartFromFailurePoint() throws Exception {
// Given - simulates mid-processing error
insertTestOrders(100);
insertPoisonOrder(50); // Causes an error
// When - first execution fails
JobExecution firstExecution = jobLauncherTestUtils.launchJob();
assertThat(firstExecution.getStatus()).isEqualTo(BatchStatus.FAILED);
// Fix the data
removePoisonOrder(50);
// When - restart
JobExecution restartExecution = jobLauncherTestUtils.launchJob(
firstExecution.getJobParameters());
// Then - resumes from failure point
assertThat(restartExecution.getStatus()).isEqualTo(BatchStatus.COMPLETED);
}
private void insertTestOrders(int count) {
for (int i = 1; i <= count; i++) {
jdbcTemplate.update(
"INSERT INTO orders (id, customer_id, amount, status) VALUES (?, ?, ?, 'PENDING')",
i, i * 10, BigDecimal.valueOf(i * 10));
}
}
private int countProcessedOrders() {
return jdbcTemplate.queryForObject(
"SELECT COUNT(*) FROM processed_orders", Integer.class);
}
}Question 15: How to optimize database write performance?
Writing often becomes the bottleneck. Optimizations include: JDBC batch inserts, disabling constraints during loading, and using staging tables.
// Writer optimized for high volumes
@Component
public class OptimizedJdbcWriter implements ItemWriter<ProcessedOrder> {

    private final JdbcTemplate jdbcTemplate;
    private final DataSource dataSource;

    public OptimizedJdbcWriter(JdbcTemplate jdbcTemplate, DataSource dataSource) {
        this.jdbcTemplate = jdbcTemplate;
        this.dataSource = dataSource;
    }

    @Override
    public void write(Chunk<? extends ProcessedOrder> chunk) throws Exception {
        List<? extends ProcessedOrder> items = chunk.getItems();

        if (items.isEmpty()) {
            return;
        }

        // Uses PreparedStatement with batch
        try (Connection connection = dataSource.getConnection();
             PreparedStatement ps = connection.prepareStatement(
                     "INSERT INTO processed_orders (order_id, customer_id, final_price, processed_at) " +
                             "VALUES (?, ?, ?, ?)")) {

            for (ProcessedOrder order : items) {
                ps.setLong(1, order.orderId());
                ps.setLong(2, order.customerId());
                ps.setBigDecimal(3, order.finalPrice());
                ps.setTimestamp(4, Timestamp.valueOf(order.processedAt()));
                ps.addBatch();
            }

            // Executes all inserts in a single network operation
            ps.executeBatch();
        }
    }
}

// StagingTableWriter.java
// Staging table pattern for very large volumes
@Component
public class StagingTableWriter implements ItemWriter<ProcessedOrder>, StepExecutionListener {

    private final JdbcTemplate jdbcTemplate;
    private String stagingTable;

    public StagingTableWriter(JdbcTemplate jdbcTemplate) {
        this.jdbcTemplate = jdbcTemplate;
    }

    @Override
    public void beforeStep(StepExecution stepExecution) {
        // Creates a temporary table for this step
        stagingTable = "staging_orders_" + stepExecution.getId();
        jdbcTemplate.execute(
                "CREATE TEMP TABLE " + stagingTable + " (LIKE processed_orders INCLUDING ALL)");
    }

    @Override
    public void write(Chunk<? extends ProcessedOrder> chunk) {
        // Writes to staging table (without FK constraints)
        String sql = "INSERT INTO " + stagingTable +
                " (order_id, customer_id, final_price, processed_at) VALUES (?, ?, ?, ?)";

        jdbcTemplate.batchUpdate(sql, chunk.getItems(), chunk.size(),
                (ps, order) -> {
                    ps.setLong(1, order.orderId());
                    ps.setLong(2, order.customerId());
                    ps.setBigDecimal(3, order.finalPrice());
                    ps.setTimestamp(4, Timestamp.valueOf(order.processedAt()));
                });
    }

    @Override
    public ExitStatus afterStep(StepExecution stepExecution) {
        if (stepExecution.getStatus() == BatchStatus.COMPLETED) {
            // Bulk copy to final table
            jdbcTemplate.execute(
                    "INSERT INTO processed_orders SELECT * FROM " + stagingTable);
        }
        // Cleans up staging table
        jdbcTemplate.execute("DROP TABLE IF EXISTS " + stagingTable);
        return stepExecution.getExitStatus();
    }
}
Conclusion
Mastering Spring Batch 5 in technical interviews relies on deep understanding of internal mechanisms:
✅ Architecture: Job → Step → Chunk (Reader, Processor, Writer)
✅ Chunk processing: sizing, lifecycle, transactions
✅ Partitioning: local vs remote, partition balancing
✅ Fault tolerance: skip, retry, restart with appropriate policy
✅ Scaling: multi-threading, parallel steps, remote chunking
✅ Testing: unit, integration, end-to-end
✅ Optimization: batch writes, staging tables, monitoring
Advanced questions test the ability to justify architectural choices based on context: data volume, time constraints, error tolerance, and available infrastructure.
Start practicing!
Test your knowledge with our interview simulators and technical tests.
Can you spot the bug in Spring Boot?
One real snippet, one hidden bug, one attempt a day. No account needed to try.

Written by
Anthony Fillion-MailletFounder of SharpSkill
Full-stack developer for over 10 years. Runs SharpSkill and answers for everything published here.
Updated on March 31, 2026
Tags
Share
Related articles
Spring Modulith: Modular Monolith Architecture Explained
Learn Spring Modulith to build modular monoliths in Java. Architecture, modules, async events, testing and observability with Spring Boot 3 and 4 code examples.
Spring Boot Interview: Transaction Propagation Explained
Master Spring Boot transaction propagation: REQUIRED, REQUIRES_NEW, NESTED and more. 12 interview questions with code examples and common pitfalls.
Spring Security 6: Complete JWT Authentication
Practical guide to implementing JWT authentication with Spring Security 6. Configuration, token generation, validation, and security best practices.