Spring Boot MicrometerとPrometheus: 本番環境のActuatorメトリクス
Spring Boot 4でのSpring Boot MicrometerとPrometheusの統合: Actuatorのアクセスモデル、スクレイピング設定、HTTPメトリクス、ヘルスプローブ、アラートルール。
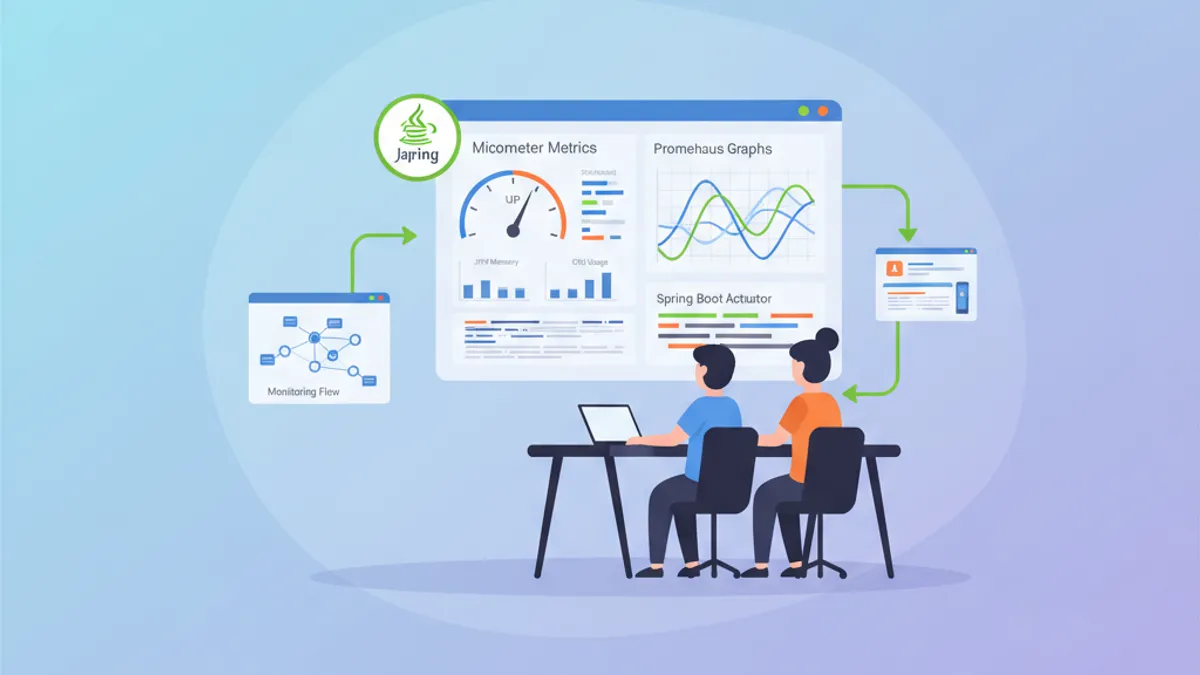
Spring Boot Actuatorはヘルス、メトリクス、診断のエンドポイントを公開し、その背後でメトリクスのファサードとして動くのがMicrometerです。micrometer-registry-prometheus 依存関係を追加すると /actuator/prometheus エンドポイントが用意され、Prometheusが一定間隔でスクレイピングします。以下の例はSpring Boot 4.1(現行GA、4.2はリリース候補段階)、Micrometer 1.16、Prometheus Javaクライアント1.xを対象としています。
Spring Boot MicrometerとPrometheusの統合は3ステップです。spring-boot-starter-actuator と micrometer-registry-prometheus を追加し、management.endpoints.web.exposure.include に prometheus を加え、Prometheusの scrape_config を /actuator/prometheus に向けます。JVM、HTTP、HikariCP、システムのメトリクスは追加コードなしで公開されます。
Spring Boot Micrometerのセットアップ: ActuatorとPrometheusレジストリ
必要な Maven 依存関係
Actuatorスターターはエンドポイントを有効化し、Micrometerを取り込みます。Prometheusレジストリはすべてのメーターを Prometheus exposition format に整形します。AspectJスターターが必要になるのは @Timed と @Counted アノテーションを使う場合だけです。
<!-- pom.xml -->
<!-- Actuator + Micrometer + Prometheus (Spring Boot 4.x) -->
<dependencies>
    <!-- Spring Boot Actuator: monitoring endpoints, includes Micrometer -->
    <dependency>
        <groupId>org.springframework.boot</groupId>
        <artifactId>spring-boot-starter-actuator</artifactId>
    </dependency>

    <!-- Micrometer Registry Prometheus (Prometheus Java client 1.x) -->
    <!-- Exposes metrics in Prometheus format at /actuator/prometheus -->
    <dependency>
        <groupId>io.micrometer</groupId>
        <artifactId>micrometer-registry-prometheus</artifactId>
    </dependency>

    <!-- AspectJ for @Timed and @Counted -->
    <!-- Spring Boot 4 renamed spring-boot-starter-aop to spring-boot-starter-aspectj -->
    <dependency>
        <groupId>org.springframework.boot</groupId>
        <artifactId>spring-boot-starter-aspectj</artifactId>
    </dependency>
</dependencies>
古いチュートリアルには、バージョンに関する落とし穴が2つあります。Micrometer 1.13(Spring Boot 3.3)以降、micrometer-registry-prometheus はPrometheus Javaクライアント1.x上に構築されています。旧0.x系のコードは非推奨の micrometer-registry-prometheus-simpleclient モジュールに残っており、Micrometer Prometheusドキュメントでは暫定的な手段としてのみ扱われています。また、Spring Boot 4では spring-boot-starter-aop を宣言したままの pom.xml は依存関係を解決できません。Spring Boot 4.0移行ガイドにより spring-boot-starter-aspectj へ名称が変更されたためです。
Actuatorエンドポイントの設定
デフォルトでHTTP上に公開されるのは health エンドポイントのみです。/actuator/prometheus エンドポイントはレジストリがクラスパスにあれば存在しますが、公開リストに追加するまでは404を返します。
Spring Boot 3.4では、オン/オフのスイッチ(management.endpoints.enabled-by-default、management.endpoint.<id>.enabled)がアクセスモデルに置き換えられ、旧プロパティは非推奨になりました。オプトイン方式では、デフォルトのアクセスを none にし、エンドポイントごとに read-only を付与します。
# application.yml
# Actuator configuration for production (Spring Boot 3.4+ access model)
management:
  endpoints:
    # Every endpoint is inaccessible unless granted below
    access:
      default: none
    web:
      exposure:
        # Endpoints exposed over HTTP
        # health, info, prometheus are the minimum for monitoring
        include: health,info,prometheus,metrics,env,loggers
      base-path: /actuator
  endpoint:
    health:
      access: read-only
      show-details: when-authorized
      show-components: when-authorized
    info:
      access: read-only
    prometheus:
      access: read-only
    metrics:
      access: read-only
    env:
      access: read-only
      # Mask sensitive values for anonymous callers
      show-values: when-authorized
    loggers:
      # unrestricted allows POST to change a log level at runtime
access: unrestricted公開とアクセスは別々の制御です。exposure.include はエンドポイントをHTTPにマッピングするかどうかを決め、access はマッピング後にエンドポイントが何を許可するかを決めます。enabled: true を使い続けているプロパティファイルは非推奨の警告付きで動作し続けるため、その警告が移行のタイミングになります。
show-details: when-authorized を指定すると、適切なロールを持つ認証済みユーザーにのみヘルスの詳細が表示されます。エンドポイント自体は専用の SecurityFilterChain で保護します。
// Securing Actuator endpoints (Spring Boot 4, Spring Security 7)
package com.example.monitoring.config;

import static org.springframework.security.web.access.IpAddressAuthorizationManager.hasIpAddress;

import org.springframework.boot.security.autoconfigure.actuate.web.servlet.EndpointRequest;
import org.springframework.context.annotation.Bean;
import org.springframework.context.annotation.Configuration;
import org.springframework.security.config.annotation.web.builders.HttpSecurity;
import org.springframework.security.web.SecurityFilterChain;

@Configuration(proxyBeanMethods = false)
public class ActuatorSecurityConfig {

    @Bean
    SecurityFilterChain actuatorSecurityFilterChain(HttpSecurity http) throws Exception {
        return http
            .securityMatcher(EndpointRequest.toAnyEndpoint())
            .authorizeHttpRequests(auth -> auth
                // Health and info public for load balancers
                .requestMatchers(EndpointRequest.to("health", "info")).permitAll()
                // Prometheus accessible from the internal network only
                .requestMatchers(EndpointRequest.to("prometheus")).access(hasIpAddress("10.0.0.0/8"))
                // Other endpoints restricted to admins
                .anyRequest().hasRole("ACTUATOR_ADMIN")
            )
            .httpBasic(basic -> {})
            .build();
    }
}
Spring Boot 4では EndpointRequest が org.springframework.boot.security.autoconfigure.actuate.web.servlet に移動しました。Actuatorエンドポイントのリファレンスのとおりです。authorizeHttpRequests のJava AuthorizedUrl DSLには hasIpAddress メソッドがありません。IPによる制限は、Spring Security 6.3から利用できる IpAddressAuthorizationManager.hasIpAddress を通して指定します。
Micrometer によるカスタムメトリクス
アプリケーションのカウンタ、ゲージ、タイマー
Micrometerは用途に応じた複数のメトリクスを提供します。Counterは累積イベント、Gaugeは瞬時値、Timerは処理時間の計測に向いています。
// Custom business metrics service
package com.example.monitoring.metrics;

import io.micrometer.core.instrument.Counter;
import io.micrometer.core.instrument.Gauge;
import io.micrometer.core.instrument.MeterRegistry;
import io.micrometer.core.instrument.Timer;
import org.springframework.stereotype.Service;

import java.util.concurrent.atomic.AtomicInteger;
import java.util.function.Supplier;

@Service
public class OrderMetricsService {

    // Counter for orders created
    private final Counter ordersCreatedCounter;
    // Timer to measure processing duration
    private final Timer orderProcessingTimer;
    // Atomic value for pending orders gauge
    private final AtomicInteger pendingOrdersCount = new AtomicInteger(0);

    public OrderMetricsService(MeterRegistry registry) {
        // Exported as orders_created_total: the _total suffix is added by the registry
        this.ordersCreatedCounter = Counter.builder("orders.created")
            .description("Total number of orders created")
            .tag("channel", "web")
            .register(registry);

        // Timer with histogram buckets: percentiles computed server-side in PromQL
        this.orderProcessingTimer = Timer.builder("orders.processing.duration")
            .description("Order processing duration")
            .publishPercentileHistogram()
            .register(registry);

        // Gauge linked to atomic value
        // Read on each scrape
        Gauge.builder("orders.pending.count", pendingOrdersCount, AtomicInteger::get)
            .description("Number of orders pending processing")
            .register(registry);
    }

    public void recordOrderCreated() {
        ordersCreatedCounter.increment();
        pendingOrdersCount.incrementAndGet();
    }

    public void recordOrderProcessed(Runnable processingLogic) {
        // Measures execution duration
        orderProcessingTimer.record(processingLogic);
        pendingOrdersCount.decrementAndGet();
    }

    public <T> T recordOrderProcessedWithResult(Supplier<T> processingLogic) {
        return orderProcessingTimer.record(processingLogic);
    }
}Prometheusレジストリでは、命名に関する2つの細部が影響します。Micrometerのメーター名はドット区切りで、スネークケースに変換されます(orders.processing.duration は orders_processing_duration_seconds になります)。Counterには _total サフィックスが自動で付くため、Counterに orders.created.total と名付けてもノイズが増えるだけです。
publishPercentiles(0.5, 0.95, 0.99) はパーセンタイルを各JVM内で計算し、その値はインスタンス間で集約できません。publishPercentileHistogram() はバケットを公開し、histogram_quantile() がフリート全体で集約します。Prometheusを使う場合はこちらを選びます。
@Timed と @Counted アノテーション
ボイラープレートを避けるため、MicrometerはAspectJを通じてメソッドを計測するアノテーションを提供しています。
// Automatic instrumentation with annotations
package com.example.monitoring.service;

import io.micrometer.core.annotation.Counted;
import io.micrometer.core.annotation.Timed;
import org.springframework.stereotype.Service;

@Service
public class PaymentService {

    private final PaymentValidator paymentValidator;

    public PaymentService(PaymentValidator paymentValidator) {
        this.paymentValidator = paymentValidator;
    }

    // @Timed creates a Timer
    // Measures each call and publishes count, sum, max and histogram buckets
    @Timed(
        value = "payment.process.duration",
        description = "Payment processing duration",
        histogram = true
    )
    public PaymentResult processPayment(PaymentRequest request) {
        // Call through another bean: the proxy intercepts it
        paymentValidator.validate(request);
        return executePayment(request);
    }

    // @Counted increments a counter on each call
    // Useful for discrete events
    @Counted(
        value = "payment.refunds",
        description = "Total number of refunds"
    )
    public void refundPayment(String transactionId) {
        // Refund logic
    }
}# application.yml
# Enables TimedAspect, CountedAspect and the other Micrometer annotation aspects
management:
observations:
annotations:
enabled: trueSpring Boot 3.2以降、TimedAspect と CountedAspect のBeanを手動で宣言する必要はありません。spring-boot-starter-aspectj をクラスパスに置いたうえで management.observations.annotations.enabled=true を設定すれば自動構成されます。このプロパティのデフォルトは false であり、「@Timedが何もしない」という報告の大半はこれが原因です。
@Timed および @Counted アノテーションは、プロキシ経由で呼び出されるSpring Beanのpublicメソッドでのみ機能します。同一クラス内のメソッド間の呼び出しはプロキシを経由しないため計測されず、privateメソッドに付けたアノテーションは無視されます。すでに計測されているSpring MVCコントローラーにアノテーションを付けると、オブザベーションが重複します。
Spring Bootの面接対策はできていますか?
インタラクティブなシミュレーター、flashcards、技術テストで練習しましょう。
カスタムヘルスエンドポイント
ビジネスHealth Indicator
Health Indicator は外部依存や重要な業務コンポーネントの状態を確認します。Spring Bootはデータベース、Redis、その他一般的なサービス向けの標準インジケーターを提供しています。Spring Boot 4ではヘルスAPIが独立した spring-boot-health モジュールに移り、Health と HealthIndicator は org.springframework.boot.actuate.health から org.springframework.boot.health.contributor に移動しました。
// Health indicator for payment gateway (Spring Boot 4 packages)
package com.example.monitoring.health;

import org.springframework.boot.health.contributor.Health;
import org.springframework.boot.health.contributor.HealthIndicator;
import org.springframework.stereotype.Component;
import org.springframework.web.client.RestClient;

import java.time.Duration;
import java.time.Instant;

@Component
public class PaymentGatewayHealthIndicator implements HealthIndicator {

    private final RestClient restClient;
    private final String gatewayHealthUrl;

    public PaymentGatewayHealthIndicator(RestClient.Builder restClientBuilder) {
        this.restClient = restClientBuilder.build();
        this.gatewayHealthUrl = "https://api.payment-gateway.com/health";
    }

    @Override
    public Health health() {
        Instant start = Instant.now();

        try {
            // Call gateway health endpoint
            var response = restClient.get()
                .uri(gatewayHealthUrl)
                .retrieve()
                .toBodilessEntity();

            Duration responseTime = Duration.between(start, Instant.now());

            if (response.getStatusCode().is2xxSuccessful()) {
                return Health.up()
                    .withDetail("responseTime", responseTime.toMillis() + "ms")
                    .withDetail("statusCode", response.getStatusCode().value())
                    .build();
            } else {
                return Health.down()
                    .withDetail("statusCode", response.getStatusCode().value())
                    .withDetail("reason", "Unexpected status code")
                    .build();
            }
        } catch (Exception e) {
            Duration responseTime = Duration.between(start, Instant.now());

            return Health.down()
                .withDetail("error", e.getClass().getSimpleName())
                .withDetail("message", e.getMessage())
                .withDetail("responseTime", responseTime.toMillis() + "ms")
                .build();
        }
    }
}
このインジケーターは /actuator/health 配下に paymentGateway という名前で表示されます。Bean名から HealthIndicator サフィックスを除いた名前です。
Kubernetes 向けのヘルスグループ
Spring Boot 4では、Kubernetesを検出した場合に限らず、すべてのプラットフォームでlivenessとreadinessのプローブがデフォルトで有効です。/actuator/health/liveness と /actuator/health/readiness のグループは設定なしで存在し、LivenessStateHealthIndicator や ReadinessStateHealthIndicator のBeanを手動で宣言する必要はありません。設定が必要になるのは、グループにコンポーネントを追加する場合か、カスタムグループを定義する場合だけです。
# application.yml
# Health groups configuration for Kubernetes
management:
  endpoint:
    health:
      probes:
        # true by default in Spring Boot 4
        enabled: true
        # Also serve the groups at /livez and /readyz on the main server port
        add-additional-paths: true
      group:
        # Readiness: can the application receive traffic?
        readiness:
          include: readinessState,db
        # Custom group for critical dependencies
        critical:
          include: db,paymentGateway
          show-details: when-authorized
livenessグループは livenessState のみに留めるべきです。データベースや外部ゲートウェイをlivenessに含めると、その依存先が落ちた時点でKubernetesがすべてのPodを再起動し、部分的な障害が全面障害に変わります。外部依存はreadinessに入れ、それもアプリケーションがその依存なしでは一切のリクエストを処理できない場合に限ります。
Kubernetes のプローブは専用のエンドポイントを参照するように設定します。
# kubernetes-deployment.yml
# Kubernetes probes configuration
spec:
  containers:
    - name: order-service
      livenessProbe:
        httpGet:
          path: /livez
          port: 8080
        initialDelaySeconds: 30
        periodSeconds: 10
        failureThreshold: 3
      readinessProbe:
        httpGet:
          path: /readyz
          port: 8080
        initialDelaySeconds: 10
        periodSeconds: 5
        failureThreshold: 3
add-additional-paths: true を指定すると、Actuatorが別の管理ポートで動いている場合でもプローブはアプリケーションポート上に残るため、メインサーバーの故障をプローブで検知できます。
Spring Boot と Prometheus の統合、そして Grafana
Prometheus のスクレイピング設定
Prometheusは /actuator/prometheus エンドポイントを定期的に問い合わせてメトリクスを収集します。Prometheusのデフォルトのパスは /metrics であるため、スクレイピング設定ではターゲットとメトリクスのパスを定義します。
# prometheus.yml
# Prometheus configuration for Spring Boot
global:
  scrape_interval: 15s
  evaluation_interval: 15s

scrape_configs:
  - job_name: 'spring-boot-apps'
    metrics_path: '/actuator/prometheus'
    scrape_interval: 10s
    static_configs:
      - targets:
          - 'order-service:9090'
          - 'payment-service:9090'
          - 'inventory-service:9090'
    # Relabeling to strip the port from the instance label
    relabel_configs:
      - source_labels: [__address__]
        target_label: instance
        regex: '([^:]+):\d+'
        replacement: '${1}'

  # Kubernetes service discovery
  - job_name: 'kubernetes-pods'
    kubernetes_sd_configs:
      - role: pod
    relabel_configs:
      # Only scrape pods with annotation
      - source_labels: [__meta_kubernetes_pod_annotation_prometheus_io_scrape]
        action: keep
        regex: true
      - source_labels: [__meta_kubernetes_pod_annotation_prometheus_io_path]
        action: replace
        target_label: __metrics_path__
regex: (.+)ターゲットがポート9090を使っているのは、後述の本番構成でActuatorを別の管理ポートに移しているためです。management.server.port を設定しない場合、スクレイピング対象はアプリケーションのポートになります。
Spring Boot Actuatorがデフォルトで公開するメトリクス
Micrometerと組み合わせたActuatorは、JVM、プロセス、HikariCP、HTTPのメトリクスをコードなしで公開します。本番で最初に監視するものは、以下のPromQLクエリでカバーできます。
# PromQL queries for JVM monitoring

# Heap memory usage, summed across heap pools
sum by (instance) (jvm_memory_used_bytes{area="heap"})

# Heap usage percentage
sum by (instance) (jvm_memory_used_bytes{area="heap"})
  / sum by (instance) (jvm_memory_max_bytes{area="heap"}) * 100

# Live threads
jvm_threads_live_threads

# Garbage collection: seconds spent paused per second
rate(jvm_gc_pause_seconds_sum[5m])

# GC pauses per minute
rate(jvm_gc_pause_seconds_count[1m]) * 60

# CPU used by the JVM process
process_cpu_usage

# Active database connections
hikaricp_connections_active

# Connection pool utilization
hikaricp_connections_active / hikaricp_connections_max * 100
jvm_memory_used_bytes{area="heap"} はメモリプールごと(G1ではEden、Survivor、Old Gen)に1系列を返します。sum by (instance) を使わずに最大値で割ると、プールごとの比率になり、ダッシュボード上では誤った値に見えます。
デフォルトでカバーされないアプリケーションレベルのゲージは、MeterBinder Beanで追加します。
// Additional JVM metrics
package com.example.monitoring.metrics;

import io.micrometer.core.instrument.Gauge;
import io.micrometer.core.instrument.MeterRegistry;
import io.micrometer.core.instrument.binder.MeterBinder;
import org.springframework.stereotype.Component;

import java.lang.management.ManagementFactory;
import java.lang.management.OperatingSystemMXBean;

@Component
public class CustomJvmMetrics implements MeterBinder {

    @Override
    public void bindTo(MeterRegistry registry) {
        OperatingSystemMXBean osBean = ManagementFactory.getOperatingSystemMXBean();

        // System load average
        Gauge.builder("system.load.average", osBean, OperatingSystemMXBean::getSystemLoadAverage)
            .description("System load average over 1 minute")
            .register(registry);

        // Available processors count
        Gauge.builder("system.cpu.count", osBean, OperatingSystemMXBean::getAvailableProcessors)
            .description("Number of available processors")
            .register(registry);

        // Application uptime
        Gauge.builder("application.uptime.seconds",
                ManagementFactory.getRuntimeMXBean(),
                bean -> bean.getUptime() / 1000.0)
            .description("Application uptime in seconds")
            .register(registry);
    }
}
system.cpu.count と process.uptime はMicrometerの組み込みバインダーがすでに公開しています。この例はパターンを示すためのもので、実際のバインダーではデフォルトに欠けているものだけを登録します。
すぐに使えるGrafanaダッシュボード
Grafanaには、標準のActuatorメトリクスで動作するSpring Boot向けのコミュニティダッシュボードがあります。手書きのダッシュボードでは timeseries と stat のパネルタイプを使います。
{
  "annotations": {
    "list": []
  },
  "panels": [
    {
      "title": "Request Rate",
      "type": "timeseries",
      "targets": [
        {
          "expr": "sum by (method, uri, status) (rate(http_server_requests_seconds_count{application=\"$application\"}[5m]))",
          "legendFormat": "{{method}} {{uri}} - {{status}}"
        }
      ]
    },
    {
      "title": "Response Time P99",
      "type": "timeseries",
      "targets": [
        {
          "expr": "histogram_quantile(0.99, sum by (le, method, uri) (rate(http_server_requests_seconds_bucket{application=\"$application\"}[5m])))",
          "legendFormat": "{{method}} {{uri}}"
        }
      ]
    },
    {
      "title": "Error Rate",
      "type": "stat",
      "targets": [
        {
          "expr": "sum(rate(http_server_requests_seconds_count{application=\"$application\",status=~\"5..\"}[5m])) / sum(rate(http_server_requests_seconds_count{application=\"$application\"}[5m])) * 100"
        }
      ]
    }
  ]
}
古いチュートリアルからコピーされたダッシュボードの多くは、いまだに graph と singlestat のパネルタイプを使っています。SinglestatはGrafana 8で削除され、Grafana 12ではAngularJSのサポートが完全に削除されたため、これらのパネルは timeseries と stat に移行しない限り表示されません。
コミュニティダッシュボードのインポート手順: Grafana > Dashboards > New > Import を開き、ID 4701 (JVM Micrometer) または 12900 (SpringBoot APM) を入力します。インポート後はパネルタイプを確認してください。コミュニティダッシュボードの古いリビジョンには、Grafana 12が移行しなければならないAngularパネルが残っている場合があります。
Prometheus によるアラート
必須のアラートルール
Prometheusのアラートルールは、メトリクスが重要なしきい値を超えた際に通知を発行します。
# alerting-rules.yml
# Alert rules for Spring Boot applications
groups:
  - name: spring-boot-alerts
    rules:
      # Alert if application is down
      - alert: ApplicationDown
        expr: up{job="spring-boot-apps"} == 0
        for: 1m
        labels:
          severity: critical
        annotations:
          summary: "Application {{ $labels.instance }} is down"
          description: "{{ $labels.instance }} has been down for more than 1 minute"

      # Alert on HTTP error rate
      - alert: HighErrorRate
        expr: |
          sum(rate(http_server_requests_seconds_count{status=~"5.."}[5m])) by (application)
          /
          sum(rate(http_server_requests_seconds_count[5m])) by (application)
          > 0.05
        for: 5m
        labels:
          severity: warning
        annotations:
          summary: "High error rate on {{ $labels.application }}"
          description: "Error rate is {{ $value | humanizePercentage }}"

      # Alert on P99 latency, aggregated per application
      - alert: HighLatency
        expr: |
          histogram_quantile(0.99,
            sum by (le, application) (rate(http_server_requests_seconds_bucket[5m]))
          ) > 2
        for: 5m
        labels:
          severity: warning
        annotations:
          summary: "High latency on {{ $labels.application }}"
          description: "P99 latency is {{ $value | humanizeDuration }}"

      # Heap memory alert
      - alert: HighHeapUsage
        expr: |
          sum by (instance) (jvm_memory_used_bytes{area="heap"})
          / sum by (instance) (jvm_memory_max_bytes{area="heap"})
          > 0.85
        for: 5m
        labels:
          severity: warning
        annotations:
          summary: "High heap memory usage on {{ $labels.instance }}"
          description: "Heap usage is at {{ $value | humanizePercentage }}"

      # Database connection pool exhausted alert
      - alert: DatabaseConnectionPoolExhausted
        expr: |
          hikaricp_connections_active
          / hikaricp_connections_max
          > 0.9
        for: 2m
        labels:
          severity: critical
        annotations:
          summary: "Database connection pool nearly exhausted"
          description: "{{ $value | humanizePercentage }} of connections in use"

      # Excessive GC alert
      - alert: HighGCPause
        expr: |
          rate(jvm_gc_pause_seconds_sum[5m])
          / rate(jvm_gc_pause_seconds_count[5m])
          > 0.5
        for: 5m
        labels:
          severity: warning
        annotations:
          summary: "High GC pause time"
description: "Average GC pause is {{ $value | humanizeDuration }}"これらのアラートは、可用性・パフォーマンス・リソースという、本番でよく発生する代表的な問題をカバーします。HighLatency ルールには sum by (le, ...) が必要です。これがないと histogram_quantile は系列ごと(URI、メソッド、ステータスごと)にP99を計算し、3回しか呼ばれていない遅いエンドポイント1つでアラートが発火します。
Spring Boot の HTTP メトリクスとデータベースメトリクス
HTTPリクエストの自動計測
Spring BootはObservation APIを通じて、Spring MVCとWebFluxのすべての受信リクエストを計測し、method、uri、status、outcome、exception のタグ付きで http.server.requests タイマーを公開します。
# application.yml
# HTTP metrics configuration
management:
  metrics:
    distribution:
      # Histogram buckets for server-side percentiles
      percentiles-histogram:
        http.server.requests: true
      # SLO buckets: count requests faster than each boundary
      slo:
        http.server.requests: 100ms, 500ms, 1s, 2s
    tags:
      # Common tags added to every meter
      application: ${spring.application.name}
      environment: ${spring.profiles.active:default}
多くのサンプルに登場する WebMvcTagsContributor と WebMvcTagsProvider インターフェースは、Spring Boot 3.0で削除されました。現在は、Spring Bootメトリクスのリファレンスに記載のとおり、DefaultServerRequestObservationConvention を継承してカスタムタグを追加します。
// Adds custom tags to http.server.requests (Spring Boot 3.0+)
package com.example.monitoring.config;

import io.micrometer.common.KeyValue;
import io.micrometer.common.KeyValues;
import org.springframework.http.server.observation.DefaultServerRequestObservationConvention;
import org.springframework.http.server.observation.ServerRequestObservationContext;
import org.springframework.stereotype.Component;

import jakarta.servlet.http.HttpServletRequest;

@Component
public class TenantObservationConvention extends DefaultServerRequestObservationConvention {

    @Override
    public KeyValues getLowCardinalityKeyValues(ServerRequestObservationContext context) {
        HttpServletRequest request = context.getCarrier();
        String userId = request.getHeader("X-User-Id");
        String tenantId = request.getHeader("X-Tenant-Id");

        // Keep the default tags and add two bounded ones
        return super.getLowCardinalityKeyValues(context).and(
            KeyValue.of("user.type", userId != null ? "authenticated" : "anonymous"),
            KeyValue.of("tenant", tenantId != null ? tenantId : "default")
        );
    }
}Prometheusのラベルになるのは低カーディナリティのキーと値だけです。tenant タグはテナントが数十なら許容範囲ですが、数千になるとカーディナリティの問題になります。高カーディナリティの値(ユーザーID、注文ID)は getHighCardinalityKeyValues に入れるべきで、こちらはトレースにのみ渡されます。Observation APIのトレース側については Spring BootのOpenTelemetryによるオブザーバビリティ で詳しく解説しています。
HikariCP と SQL クエリのメトリクス
HikariCPのプールメトリクスは hikaricp プレフィックス付きで、プール名をタグとして自動的に公開され、汎用の jdbc.connections ゲージも併せて公開されます。プール名を設定するとタグが読みやすくなります。
# application.yml
# HikariCP pool configuration
spring:
  datasource:
    hikari:
      # Becomes the "pool" tag on hikaricp_* metrics
      pool-name: OrderServicePool
      maximum-pool-size: 20
      minimum-idle: 5
      connection-timeout: 30000
      idle-timeout: 600000
      max-lifetime: 1800000
クエリ単位の実行時間はSpring Bootではカバーされません。datasource-micrometer プロジェクトは DataSource をラップし、コネクション、クエリ、結果セットごとにオブザベーションを作成するため、メトリクスとトレースのスパンの両方が得られます。2.x系はSpring Boot 4、1.x系はSpring Boot 3が対象です。
<!-- pom.xml -->
<!-- JDBC observations: 2.x for Spring Boot 4, 1.x for Spring Boot 3 -->
<dependency>
    <groupId>net.ttddyy.observation</groupId>
    <artifactId>datasource-micrometer-spring-boot</artifactId>
    <version>2.0.1</version>
</dependency>これは、DataSource を ProxyDataSourceBuilder と手書きのリスナーでラップする手動の方法に代わるものです。手動の方法はSpring Bootの DataSource 自動構成を迂回してしまい、Bootのアップグレードのたびに追従させる必要がありました。遅いクエリの多くはN+1パターンが原因であり、Spring Data JPAのN+1クエリ解決策で扱っています。
本番運用におけるベストプラクティス
メトリクスのカーディナリティ
カーディナリティが高すぎるとPrometheusのパフォーマンスが低下します。タグの一意な組み合わせごとに別々の時系列が生成されるためです。
// AVOID: unbounded cardinality
package com.example.monitoring.antipattern;

@Service
public class AntiPatternHighCardinality {

    private final MeterRegistry registry;

    // BAD: userId creates one series per user
    public void trackUserAction(String userId, String action) {
        Counter.builder("user.actions")
            .tag("userId", userId)  // Millions of possible values
            .tag("action", action)
            .register(registry)
            .increment();
    }
}// Controlled cardinality
package com.example.monitoring.bestpractice;
@Service
public class GoodPracticeCardinality {
private final MeterRegistry registry;
// GOOD: user category instead of ID
public void trackUserAction(User user, String action) {
Counter.builder("user.actions")
.tag("userType", user.getSubscriptionType()) // FREE, PREMIUM, ENTERPRISE
.tag("action", action)
.register(registry)
.increment();
}
// GOOD: let a timer histogram bucket durations
public void trackResponseTime(long responseTimeMs) {
Timer.builder("response.time")
.publishPercentileHistogram()
.register(registry)
.record(Duration.ofMillis(responseTimeMs));
}
}レイテンシに関する問いには、手作りの bucket タグを付けたCounterよりも、ヒストグラムのバケットを持つ Timer のほうが適しています。PromQLはバケットから任意のパーセンタイルを計算でき、バケットの境界もサービス間で一貫します。
本番運用向けの構成
# application-production.yml
# Production configuration (Spring Boot 4)
management:
  server:
    # Separate port for management endpoints, not exposed publicly
    port: 9090
  endpoints:
    access:
      default: none
    web:
      exposure:
        include: health,info,prometheus
  endpoint:
    health:
      access: read-only
      show-details: when-authorized
      probes:
        add-additional-paths: true
    info:
      access: read-only
    prometheus:
      access: read-only
  observations:
    annotations:
      enabled: true
  metrics:
    distribution:
      percentiles-histogram:
        http.server.requests: true
      minimum-expected-value:
        http.server.requests: 1ms
      maximum-expected-value:
        http.server.requests: 30s
    tags:
      application: ${spring.application.name}
      environment: production
      version: ${app.version:unknown}
access.default: none を指定すると、env、beans、configprops、mappings などのエンドポイントは、1つずつ列挙しなくてもアクセスできなくなります。management.prometheus.metrics.export.enabled のデフォルトは true です。また step の設定はPrometheusには効果がありません。Prometheusはプル型のレジストリであり、スクレイピング間隔は prometheus.yml で設定するためです。
ActuatorとPrometheusでよくあるエラー
| 症状 | 原因 | 対処 |
|---|---|---|
/actuator/prometheus が404を返す | エンドポイントが公開リストにない、またはレジストリがない | management.endpoints.web.exposure.include に prometheus を追加し、micrometer-registry-prometheus がクラスパスにあるか確認する |
| Prometheusのターゲットに "server returned HTTP status 401" と表示される | Spring Securityが health 以外のすべてのエンドポイントを保護している | スクレイパーのネットワークに prometheus を開放するか、スクレイピング設定でBasic認証を構成する |
@Timed でメトリクスが生成されない | management.observations.annotations.enabled がデフォルトで false、またはAspectJがない | プロパティを true にし、spring-boot-starter-aspectj を追加する |
アップグレード後に spring-boot-starter-aop が見つからない | Spring Boot 4で名称変更された | spring-boot-starter-aspectj を使う |
Boot 4で Health や HealthIndicator のimportに失敗する | パッケージが org.springframework.boot.health.contributor に移動した | importを更新する |
management.endpoint.*.enabled で非推奨の警告が出る | オン/オフのモデルがSpring Boot 3.4で置き換えられた | management.endpoints.access.default と management.endpoint.<id>.access を使う |
| ダッシュボードのパーセンタイルが実態と大きく異なる | publishPercentiles の値がPod間で平均されている | publishPercentileHistogram() と histogram_quantile() を使う |
Spring Boot Micrometerに関する面接の質問
Actuatorは、ミドルからシニアのポジション向けのSpring Boot面接の多くで話題になります。経験のある候補者とジュニアを分ける回答は次のとおりです。
- livenessとreadinessの違い: livenessはKubernetesにPodの再起動を指示し、readinessはトラフィックの振り分け停止を指示します。データベースをlivenessグループに入れる候補者は、障害時にそれを運用した経験がありません。
- Prometheusクライアントを直接使わずMicrometerを使う理由: Micrometerはファサードです。同じ
CounterやTimerのコードが、依存関係を変えるだけでPrometheus、Datadog、OTLPにエクスポートされ、Spring自身の計測(HTTP、JDBCプール、キャッシュ)もMicrometerに対して書かれています。 - クライアント側パーセンタイルとヒストグラムの違い: クライアント側のパーセンタイルはインスタンス間で集約できず、ヒストグラムは集約できます。このテーマで最もよく出るひっかけ問題です。
- カーディナリティの意味と、それがPrometheusを壊す仕組み: ラベルの一意な組み合わせごとに1つの時系列が生まれます。ユーザーIDのタグはメモリ使用量をユーザー数倍にします。
- Actuatorの保護方法: 公開範囲を絞り、アクセスレベルを設定し、管理用エンドポイントを別ポートで動かし、専用の
SecurityFilterChainで保護します。
この種の質問は Spring Boot Actuatorの面接質問 モジュールにまとめています。
参考資料
- Spring Boot 4.0 Migration Guide:
spring-boot-starter-aopからspring-boot-starter-aspectjへの名称変更、プローブのデフォルト有効化、新しいspring-boot-healthモジュール - Spring Boot 3.4 Release Notes:
enabled-by-defaultとendpoint.<id>.enabledが非推奨となり、アクセスモデルに移行 - Spring Boot Actuator endpoints reference: アクセスプロパティ、
EndpointRequestのパッケージ、org.springframework.boot.health.contributorのヘルスインジケーター、プローブグループと追加パス - Spring Boot metrics reference:
DefaultServerRequestObservationConvention、HikariCPとjdbc.connectionsのメトリクス、simpleclientの非推奨化 - Spring Boot observability reference:
management.observations.annotations.enabledとAspectJの要件 - Micrometer Prometheus documentation: Prometheus Javaクライアント1.xのレジストリと旧simpleclientモジュール
- datasource-micrometer on GitHub: 2.xはSpring Boot 4向け、1.xはSpring Boot 3向け
- Grafana: AngularJS removal in Grafana 12: GraphとSinglestatのパネルはTime seriesとStatに置き換え
- Spring Boot releases: 現行GAは4.1.2、4.2.0-RC1がプレリリース
Spring Boot MicrometerとPrometheusで押さえておくべきこと
- スクレイピングが動くまでの3ステップ: Actuatorスターター、
micrometer-registry-prometheus、公開リストへのprometheusの追加 - 3.4以降のアクセスモデル:
management.endpoints.access.default: noneとエンドポイントごとのread-onlyが、非推奨のenabledフラグに代わる - Spring Boot 4での移動:
spring-boot-starter-aspectj、ヘルスAPIはorg.springframework.boot.health.contributor、EndpointRequestはorg.springframework.boot.security.autoconfigure.actuate.web.servlet、プローブはデフォルトで有効 - アノテーションにはスイッチが必要:
management.observations.annotations.enabled=trueを設定し、TimedAspectBeanの手動宣言は不要 - HTTPタグはObservation API経由:
DefaultServerRequestObservationConventionを継承し、ラベルは低カーディナリティに保つ - クライアント側パーセンタイルよりヒストグラム:
publishPercentileHistogram()を使い、すべてのhistogram_quantileでsum by (le)を付ける - livenessはローカルに留める: 外部依存はreadinessかカスタムグループに入れ、livenessには決して入れない
これらのデフォルトにより、Spring Boot 4のサービスはPod間で正しく集約されるメトリクス、公開ネットワークに何も漏らさないエンドポイント、そして遅いURI1つではなく実際のインシデントで発火するアラートを備えることになります。
今すぐ練習を始めましょう!
面接シミュレーターと技術テストで知識をテストしましょう。
Spring Boot のバグを見つけられますか
実際のコード、隠れたバグ、1日1回。アカウントなしで試せます。

執筆
Anthony Fillion-MailletSharpSkill 創業者
10 年以上フルスタック開発に携わっています。SharpSkill を運営し、ここで公開される内容に責任を負っています。
2026年10月26日 更新
タグ
共有
関連記事
2026年のSpring Boot構造化ロギング:LogbackとOpenTelemetryによる本番JSON出力
Spring Boot 4.xの構造化ロギング完全ガイドです。ネイティブJSON出力、OpenTelemetry Starter、MDCトレーシング、本番オブザーバビリティのためのELK Stack連携を解説します。
2026年フリーランスJava Spring Boot開発者の仕事:案件の探し方、単価相場、面接対策
2026年のSpring Bootフリーランス案件市場を解説。欧州の日額単価相場、案件の見つけ方、技術面接の準備方法まで網羅した実践ガイド。
2026年のJava Spring Boot開発者の求人動向:求人の探し方、給与相場、面接対策
2026年のJava Spring Boot開発者求人の探し方、給与相場、技術要件、リモートワーク動向、面接対策を解説します。